Pick a model, then check it against the bill
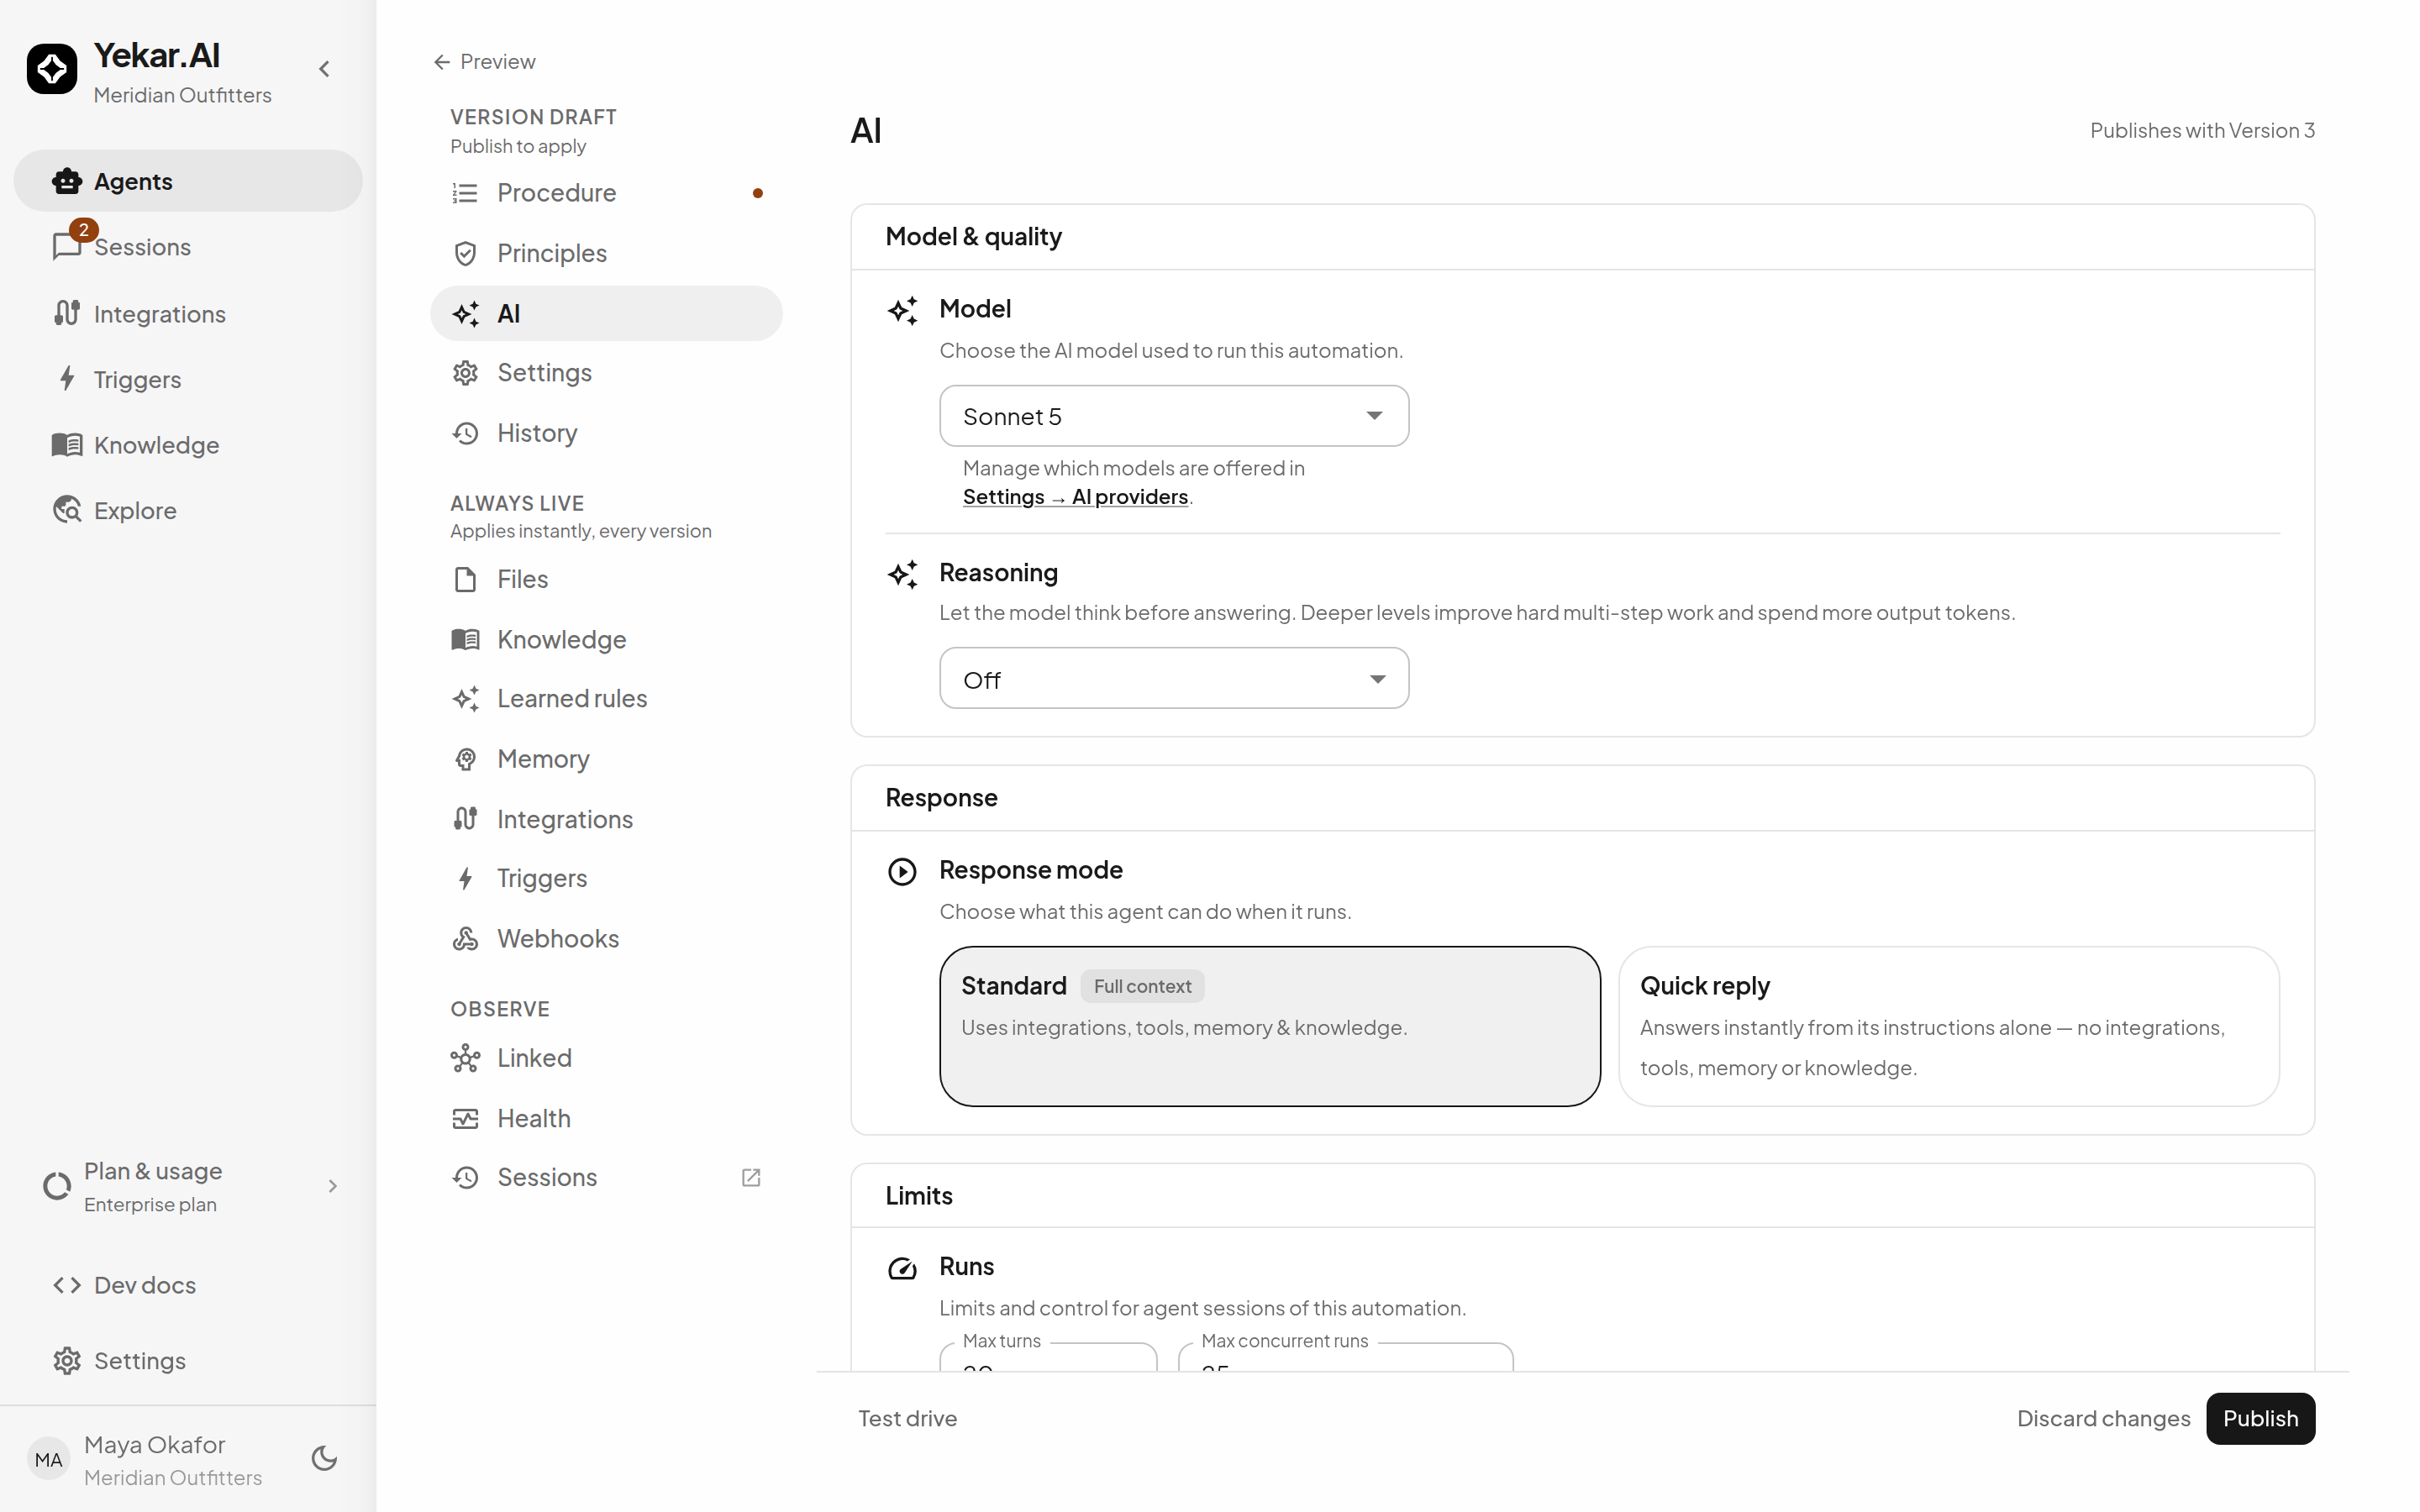
Every agent runs on one model, chosen in Setup → AI → Model or left to the organization's default. The picker offers only what the organization has turned on, so the list an author sees is the first place a provider being off shows up. AI providers is where that offering is set; this page is about choosing well within it.
Pin or default
An agent with no model pinned runs the organization's default: the preferred catalog model if its provider is configured, otherwise the most capable model of any configured provider. The picker always shows the model the next turn will actually execute - never a stale label - and a pinned model whose provider has since been turned off stays visible, flagged as unavailable, with the remedy beside it.
Pin a model when the agent's job depends on it. Leave the default for agents whose work is routine, so that a provider change is one change.
A rough guide
| Work | Choose |
|---|---|
| Routing, classification, short replies, high volume | A small fast model from the vendor you already pay |
| Judgement, multi-step tool use, long documents | A frontier model with a large context window |
| Reading images | A model with image input - the picker's hint says which; a model without it drops the image and says so |
| Deterministic flow steps with no model field | The default model |
Cost scales with tokens in and out, and a tool-heavy turn is several model rounds, each carrying the whole context again. A 1M-token window is room, not a target: Long conversations explains how a turn is trimmed to fit, and the organization can cap the window below the model's own.
Reasoning
Reasoning lets the model think before it answers. Setup → AI offers only what the chosen model has:
- Off where the model answers without thinking unless asked - Claude Opus 4.8 and Haiku 4.5, GPT-5.1, Upstage's Solar, Groq's Qwen 3.8. Off is the lowest-cost choice there.
- Model default in its place where the model thinks on its own - every Claude 5 model including the default, OpenAI's other reasoning models, Gemini, DeepSeek, Kimi K3, GLM, Grok and most hosted reasoning models. Its provider sets the depth, and that thinking is billed as output.
- Low, Medium and High buy progressively deeper thinking. Only the depths a model keeps apart are listed: where a vendor runs two of them the same (Sarvam sends High for both Medium and High), only one is offered. Where a vendor speaks low, high and max, the three step up one rung, so High is that vendor's maximum.
Each vendor implements it its own way, and Yekar.AI sends each one its own setting: Anthropic's thinking effort, OpenAI's reasoning effort, Google's thinking level, OpenRouter's reasoning effort, and the reasoning effort that DeepSeek, Kimi K3 (directly and through Together, Fireworks and NVIDIA), GLM, Grok, Mistral, Groq, Cerebras, Qwen Max, DeepInfra, Upstage's Solar and Sarvam each document. Models whose provider has no documented reasoning setting run at their provider's default, and the setting is hidden for them rather than offering a level that would not be applied. A level saved earlier that the current model does not offer stays visible with a note saying what it runs as. Raise it for an agent whose mistakes are reasoning mistakes; leave it off for one whose mistakes are missing facts.
Context windows
Each catalog entry declares its window, from 8K to 1M tokens, and a per-call output ceiling derived from it. An organization-wide Context window setting caps every agent's turn below the model's own; a per-turn meter in each session shows how much of the window that turn used and what was trimmed to fit.
What it costs, honestly
Catalog prices are metadata for estimation, not a rate card: they change when vendors change them, and a model outside the catalog has no price rather than a price of zero. What you can trust is spend: Settings → Plan & usage → Cost shows managed calls as charged actuals and own-key calls as an estimate against your provider's invoice, per agent, so a model choice is something you check against evidence after a week rather than guess. See Cost & budgets.
What the provider keeps
A model choice is also a choice of who sees the conversation. Yekar.AI asks every provider not to keep the request wherever its API allows it; beyond that, retention follows the provider's terms for the account whose key ran the call. If that matters for the material an agent handles, read what the model provider keeps before pinning a model.
What runs where the agent does not choose
Flow language-model steps without a selected model, conversation titles, summaries, and evaluations use the default model. The same provider availability rules apply, so turning a provider off affects these features too.